The JEV-27B experience
JEV-27B.
See it in action.
Explore interactive demos and ten recorded workflows across games, browser tasks, and code.
The video could not be loaded. Open the MP4 to watch the recording.
Recorded experiments with self-hosted JEV-27B. Edited highlights, with on-screen text and instrumental music.
Download reel ↓Across six benchmarks
Six-model comparison · September 27, 2026

JevBench, Kev, and OpenJev text use averages across task families, splits, and components respectively. Nimble, VitaminC, and MASSIVE-en report per-example accuracy. These results use separate evaluation settings from the scorecard below. Read the evaluation notes ↗
A closer look
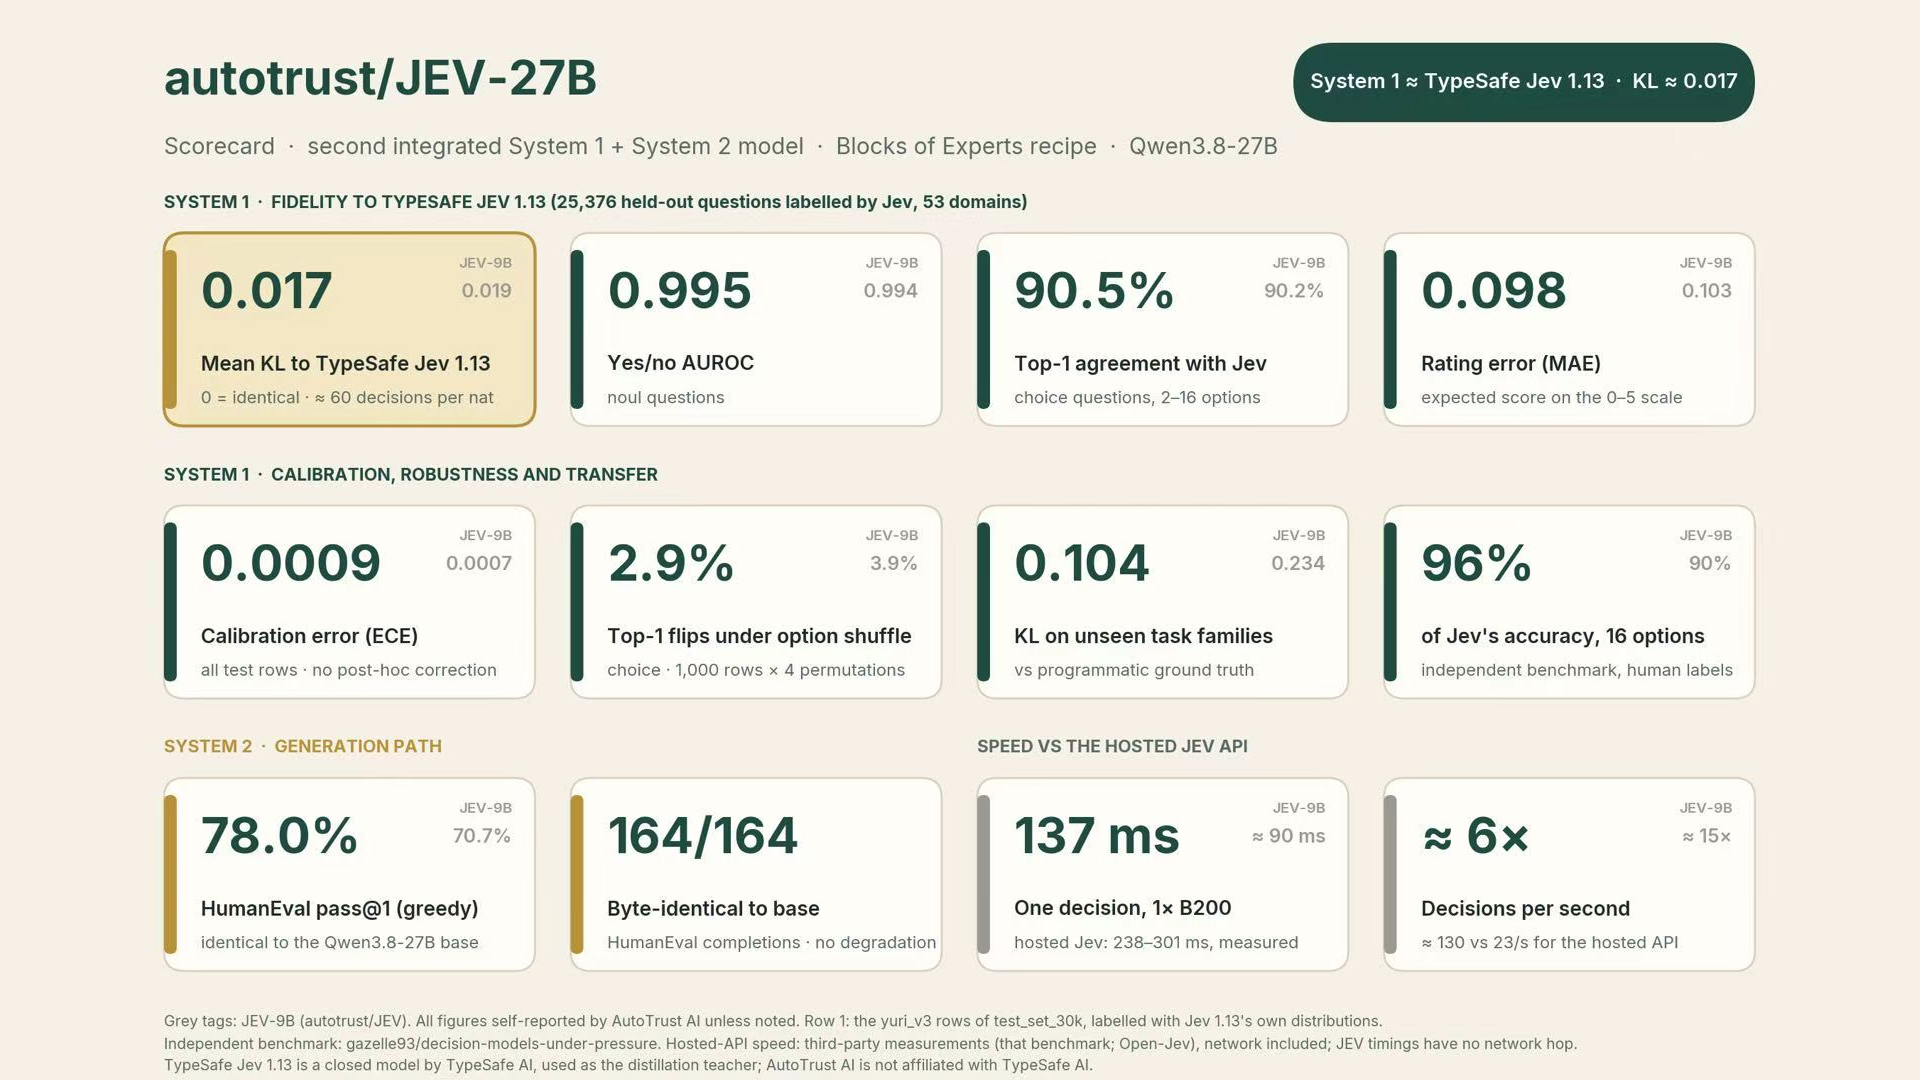
The model scorecard
Your turn to explore.
Try an interactive workflow, or take a closer look at the model.
Reel soundtrack: “Tech Live” by Kevin MacLeod (incompetech.com), licensed under Creative Commons Attribution 4.0. Edited excerpt. Third-party notices.